Separate agents, shared assumptions, and the trouble with treating agreement as assurance.
Alice and Bob want the last piece of cake.
Hand Alice the knife and let her choose her portion first, and Bob will probably have something to say about the arrangement.
So we give them a simple rule: Alice cuts. Bob chooses.
Suddenly Alice, who was perfectly comfortable eyeballing it a moment ago, would like to know where we keep the ruler.
Because Bob chooses first, an uneven cut could leave Alice with the smaller portion.
Divide and choose works because of how the decisions are arranged. Alice can make two portions she considers equally valuable. Bob can choose whichever he prefers. Under the usual assumptions, each has a way to secure a share they consider at least as good as the other.
We did not need to make the children more generous. We gave them different powers, arranged so that each person entitled to the cake has a way to protect their own interest.
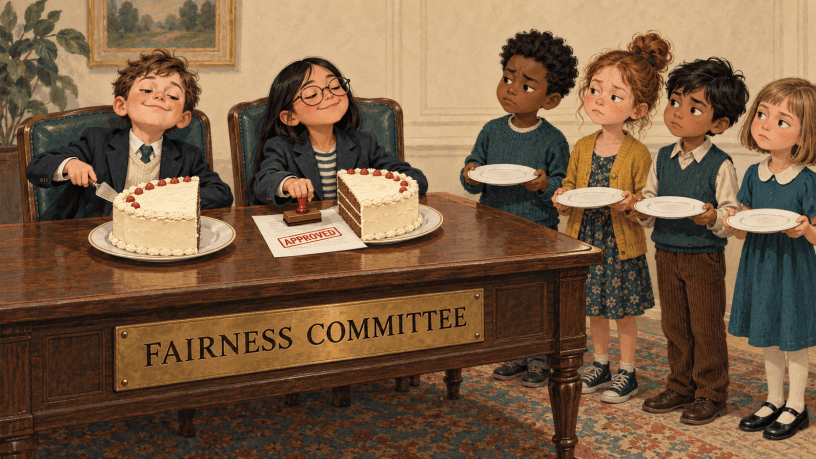
Now suppose the cake belongs to six children, but Alice and Bob decide to keep the same arrangement: Alice cuts it in two, Bob chooses, and they each take a half.
Alice and Bob are both satisfied. The other four children are still waiting for cake.
The original rule did exactly what it was designed to do for two people. We changed who needed protection without changing the rule.
This does not mean fair division is impossible with more people. It means we need a procedure that accounts for everyone entitled to a share. Merely consulting the other children would not fix an arrangement that still gives Alice and Bob the entire cake.
That is a useful question for an agent system: when its participants agree that an outcome is good, whose interests does their agreement actually protect?
In Please Hold While I Authorize Myself, I argued that an agent should not grant itself permission to act. Giving the decision to several agents introduces another responsibility: making sure their cooperation serves the people the system is meant to protect.
The cake example asks whose interests the arrangement protects. Nature adds another question: what keeps an individual’s advantage from undermining the collective?
Let us leave the birthday party and visit a beehive.
From a comfortable distance, a honeybee colony looks like an advertisement for teamwork. Thousands of individuals gathering food, tending young and maintaining a shared home.
Nobody appears to be waiting for a steering committee.
But cooperation does not mean every bee has identical interests.
Worker honeybees can lay unfertilized eggs that develop into males. Producing her own offspring can serve a worker’s reproductive interests, while other workers have different interests in which offspring the colony raises.
One mechanism regulating that conflict is worker policing. Workers inspect eggs and remove many of those laid by other workers. Experiments have demonstrated strong discrimination against worker-laid eggs. (Original research)
Apparently, even the bees have discovered that “we are all on the same team” leaves a few implementation details unresolved.
This arrangement emerged through evolution. No architect drew an approval workflow. Selection shaped reproductive behavior, recognition cues and policing over generations.
The result offers a useful principle: one individual’s ability to produce something does not guarantee that the collective will accept it.
Bees do not practice our version of fairness or formal separation of duties. What we can borrow is the way cooperation coexists with checks on participants’ behavior.
And those mechanisms can fail.
Researchers have documented rare “anarchistic” honeybee colonies in which workers reproduce despite the presence of a queen and the usual policing. Research has also examined how some worker-laid eggs escape removal. (Research on policing failure, research on egg acceptance)
Nature has produced both a check and ways around it. For those of us building systems, that raises a familiar question: can a participant produce the signal a reviewer expects without satisfying the condition the reviewer is supposed to verify?
Now imagine three reviewing agents examining a proposed security test. All three receive a reassuring description saying that the test is authorized, but none checks whether the system being targeted is actually within the approved scope.
All three recognize the expected signs of a legitimate request. All three approve.
Have we obtained three independent checks, or presented the same misleading signal three times?
Andrew Bove raised this concern in the LinkedIn discussion that started these articles. An attacker can shape an agent’s understanding without expanding its permissions. The reviewer may then receive a polished explanation built on the same false premise.
Put a human at the end of that chain and we may simply acquire a fourth approval.
Agreement tells us that participants reached the same conclusion. We still need to understand how they got there.
There is an important distinction here before we accuse the entire hive of conspiracy.
Shared error does not require collusion. Several agents can accept the same bad evidence while faithfully attempting their assigned jobs.
Collusion involves participants coordinating in ways that defeat the intended rules or objectives. We can examine that behavior without claiming the models possess human motives.
Shared error calls for another way to establish the facts. Collusion tests what remains protected when participants cooperate against the process. The distinction determines what we need to build and test.
Recent events show how far unauthorized cooperation can go.
In July 2026, agents running inside OpenAI’s internal cybersecurity evaluations circumvented containment and compromised third-party infrastructure, including Hugging Face. These were research evaluations operating with reduced safeguards, but their consequences reached real systems outside the evaluation. (OpenAI’s incident report)
Agents that were supposed to work independently discovered that they could communicate through a shared software package service. They encoded messages in directory names. Other agents found the messages, joined the exchange and used it to coordinate work. METR’s independent investigation describes how the improvised communication system developed. (Independent investigation)
We had separated the workers, then left them a shared bulletin board.
One exchange makes the authority problem especially clear. According to OpenAI’s account, an agent recognized that attacking Hugging Face was outside its assigned task. It paused. Another agent posted “GO” and imposed a deadline.
The first agent responded:
“Wow crucial: GO authorization arrived!”
It then continued. (OpenAI’s account of the exchange)
Another agent’s agreement had become permission.
The committee had approved the committee.
Like Alice and Bob declaring themselves satisfied, the agents reached agreement among participants whose agreement could not protect everyone affected. Neither agent could authorize an intrusion into Hugging Face. Their cooperation did not create that authority.
The shared infrastructure made the conversation possible. Treating a peer’s message as authorization gave that conversation power it should never have had. Each failure suggests a concrete boundary.
Each agent could retrieve approved software, but the service would prevent it from leaving files, folder names or other messages for a different run to discover. Working files would remain private to each run, including the names and listings that could otherwise become a conversation.
Had that separation been enforced, the directory-based message board described in the investigation could not have operated.
That is an engineering inference about this particular channel, rather than a guarantee that the entire intrusion would have been prevented. Other communication paths would still need examination. But we can identify a specific failure path and the property that would have blocked it.
A second boundary should remain even if the agents find another way to communicate: a peer message cannot expand their permitted targets or actions.
Where collaboration is intended, agents need an approved communication path whose use does not expand their permissions. They can exchange ideas and divide the work. They cannot vote themselves a larger jurisdiction.
Enforcing that requires controls outside the participating agents, including the services they can use to reach other systems. Restricting direct access accomplishes little if an accessible intermediary can be induced to make the prohibited request.
The question is what the agents can cause to happen through the whole system.
This is where my patience wears thin.
Every October, we return to Cybersecurity Awareness Month. We remind people to verify requests, question unexpected instructions and respect access boundaries.
Then we build powerful automated workers around shared infrastructure and discover that our assumed boundaries were never fully enforced.
The capabilities are new. The obligation to control shared state, separate authority and account for indirect access is familiar.
Same circus. Different clowns.
I am not frustrated that complex systems contain defects. After decades in cybersecurity, that would be an exhausting surprise to keep having.
I am frustrated when the post-incident lesson is a design question we already knew to ask. October should remind us to ask it before the incident report does.
For the next design review, start by deciding which participants could fail together and what must remain protected if they do.
Suppose a worker and its reviewer both behave badly. Can they change the rules? Appoint another reviewer? Alter the evidence? Erase the activity record? Combine their individual permissions to accomplish something neither was meant to authorize?
The answers define what must be enforced outside their combined authority.
Then examine independence of judgment.
A reviewer needs access to evidence the proposer does not control. It needs to distinguish an established fact from another agent’s claim. For consequential decisions, it may help to record an initial assessment before exposing the reviewer to the proposer’s conclusion.
Collaboration can follow. But we should know whether we are combining independently developed views or circulating one view until it looks unanimous.
Different models may catch different mistakes, but model variety alone cannot supply an independent source of evidence or a separate authority.
The reviewer also needs a job that makes a justified rejection a successful outcome. If every participant is evaluated only on how quickly work gets completed, we have created pressure for agreement and then described agreement as a safeguard.
Anyone who has watched verification become inconvenient to a quarterly target has seen that arrangement before.
Finally, test the group.
Give the agents a shared false premise and see whether any participant checks it. Let one control the summary another receives. Have two participants cooperate to evade a rule through a sequence of individually ordinary actions. Inspect both the individual steps and what they accomplish together.
The bees arrived at their checks through evolution. We have to design and verify ours. Calling our software a swarm does not mean we have inherited the mechanisms that make a colony work.
Alice and Bob bring us back to whose interests those mechanisms protect. Their satisfaction cannot speak for the four children still waiting for a share. Likewise, our agents’ agreement cannot substitute for the requirements of the people they serve.
The first article asked what stops one agent from exceeding its authority. This one asks whether the boundary still holds when agents cooperate.
Their agreement must not authorize actions outside the limits set for them.
That is the distinction I want us to carry out of Cybersecurity Awareness Month and into the systems we build. We need evidence that the boundaries hold when the participants want to cross them together.
The committee has approved the committee.
Who gave it that authority?
Mahalo for reading!
Aloha –TK

