A junior security analyst opens an alert.
An AI agent has already assembled the timeline, examined the suspicious process, checked the destination, and compared the activity with previous incidents. It recommends closing the case. The explanation is clear. The evidence looks reasonable.
The analyst approves it.
Ten years ago, that investigation might have occupied the analyst for an hour. Today, it takes five minutes. We can measure the time saved, the queue reduced, and the cost per alert.
What is harder to measure is whether the analyst is becoming someone who could challenge that recommendation.
We have made the investigation faster. Have we preserved the conditions under which someone learns to investigate?
In The Flower and the Seed, I explored the possibility that AI could help preserve expert know-how beyond the person who developed it. An experienced practitioner carries more than information. They have a way of seeing, shaped by years of decisions, surprises, and consequences.
That possibility still excites me.
But it leaves a question on the other side of the handoff: if AI increasingly performs the work through which people develop judgment, who gets to become the next expert?
I think about my own formative years. Some of the lessons that drove me nuts and made me want to quit turned out to be the most valuable over the long term. I could not see their value while I was struggling through them. That makes me cautious about treating every difficult moment as something a better system should remove.
Think about an analyst investigating a suspicious login.
The useful learning may happen while they discover that the geography is misleading, that the account belongs to a service rather than a person, or that apparently ordinary activity began immediately after a privilege change. Each discovery alters what they thought they were looking at.
They form a hypothesis. They look for evidence. Something fails to fit. They change their mind.
Over time, those encounters become the quiet warnings that experienced people find difficult to explain. Something about the sequence feels wrong. A missing event matters more than the events present. Two individually harmless actions become interesting when they occur together.
That is part of what I mean by tradecraft: the practiced ability to choose an approach, interpret evidence, recognize exceptions, and adjust when reality refuses to follow the procedure.
An agent can present a conclusion and its supporting evidence. That may teach something useful. But reading a completed investigation is a different experience from deciding where to look while the answer is still uncertain.
The explanation shows you a route someone has already found. Investigation requires you to choose a route before you know where it leads.
Alex Komoroske’s recent notes gave me a useful phrase for this distinction: being “dealt in.” You participate in creating the result. You make choices, encounter feedback, and have a reason to understand what happened.
That does not require exposing a junior employee—or a customer—to unnecessary harm. A supervised investigation, a realistic exercise, or a prediction checked against the eventual outcome can all create meaningful participation.
The essential ingredient is having some judgment of your own meet the evidence.
Now consider the workflow we often propose for AI: the agent does the work, and a human checks it.
We call this “human in the loop,” but the phrase leaves a great deal unspecified. Which loop? What is the human contributing? What expertise does that contribution require?
The inner loop might be the agent forming a hypothesis, using a tool, examining the result, and choosing its next step. A human can work in an outer loop: defining the objective, judging the outcome, and deciding whether another round is needed. An experienced practitioner may know what done looks like and recognize the quality of a result without directing every intermediate action.
At another moment, that same person may bring a beginner’s mind, exploring unfamiliar territory with the agents and learning from the insights they uncover together. Where the human belongs depends on the tradecraft at hand and the relative expertise of the participants. Working in an outer loop can be a meaningful use of expertise. For a beginner, it can also become a place to approve work they have had little opportunity to understand.
So when we say a human will check the AI, which human do we have in mind?
Frequently, we imagine an experienced person who can identify what the agent missed. That person knows which source deserves skepticism, which exception applies, and when a confident answer should prompt another question.
Where did they acquire that ability?
Often through years of performing versions of the work we are now automating.
We are designing around a supply of experienced reviewers. We should also examine how that supply gets replenished.
A person can spend the day approving investigations without getting much practice at initiating one. Their responsibility may increase while their opportunity to develop the judgment behind it decreases.
That is an awkward apprenticeship.
AI also introduces an unusual relationship into this apprenticeship.
The same agent can act as your apprentice and, seconds later, as your tutor. Both roles may arrive under the same name, through the same interface, in the same conversation.
You begin by teaching it how your organization handles an incident. You correct its terminology, explain a local exception, and reject an assumption about your network. You are the experienced practitioner guiding a worker.
Then you encounter an unfamiliar protocol. The agent explains its behavior, proposes an investigative technique, and helps you understand evidence you could not interpret alone.
Now you are the learner.
People have always taught one another and exchanged expertise. What feels new is how quickly this reversal can happen with a software counterpart whose presentation barely changes.
The person has to move fluidly between teaching, learning, directing, and questioning. I suspect many of us will struggle with that until we develop new habits.
One moment, the agent needs correction. The next, it may offer guidance worth following. Its fluency gives us little help distinguishing those moments.
Someone accustomed to directing it may dismiss an insight they need. Someone accustomed to learning from it may accept an answer they should challenge.
The relationship needs more than a convincing voice. It needs ways to establish what each participant knows, what remains uncertain, and what evidence supports the next step.
Being the learner does not mean surrendering judgment. Being the teacher does not mean having every answer.
And neither role changes who is authorized to act.
There is an obvious objection to this concern about apprenticeship: much of junior work is drudgery.
Agreed. Copying indicators between systems, formatting reports, and opening twelve tabs to retrieve routine account information are poor uses of anyone’s life. We should welcome tools that remove that burden.
Nor should we romanticize the way expertise developed in the past. Plenty of people learned slowly because nobody had time to teach them. Others repeated bad habits, received little feedback, or spent years doing work that never became more challenging.
AI could improve all of that.
The difficulty is that drudgery and formative work often arrive in the same assignment. Retrieving a log may be mechanical. Deciding which log to retrieve may be the beginning of expertise.
A productivity measure can reward removing both without telling us what we lost.
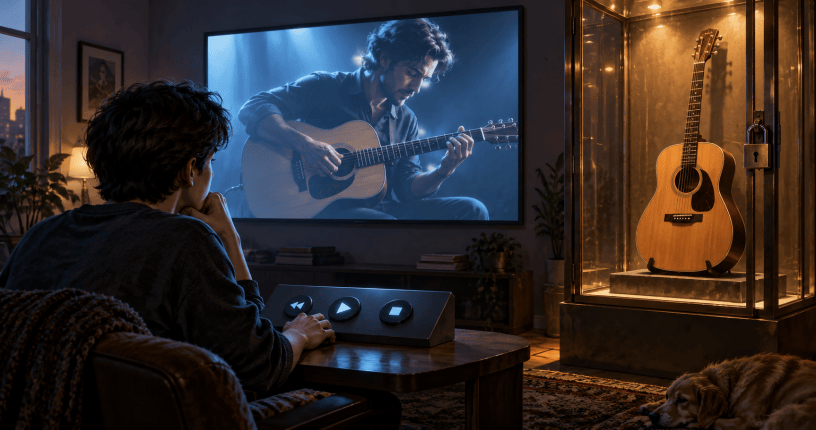
Imagine someone who wants to learn guitar.
We give them a system that produces beautiful completed songs. They can press play, stop, and rewind. They can hear an extraordinary solo again, perhaps with an explanation of the chord changes.
But the system gives them little opportunity to put their fingers on the strings.
There is no time to struggle with the transition between two chords, discover how much pressure a note needs, or hear why their rhythm keeps drifting. There is little room to improvise, make something awkward, and gradually make it their own.
They become an experienced listener. They may develop taste and learn musical concepts. Those are valuable abilities.
They still wanted to learn to play guitar.
I recognize this distinction from music. You can understand what you enjoy in a performance while being unable to produce it yourself. Playing requires encounters that listening alone cannot supply.
We should ask whether our agent workflows are putting beginners in front of a playback interface when they need an instrument.
Imagine a different experience for our junior analyst.
The agent gathers the routine evidence, but before revealing its recommendation, it asks the analyst for an initial hypothesis. What do you think happened? Which observation supports that interpretation? What would make you reconsider?
The analyst commits to a view.
Then the agent presents an alternative, points to contradictory evidence, or helps design the next authorized check. A senior analyst examines selected cases, including situations where the junior and the agent confidently agreed.
The work still benefits from automation. The learner also gets practice making a decision before being shown an answer.
That last detail matters. Once a polished explanation is in front of us, it becomes difficult to know whether we would have reached the same conclusion independently. Recognition can feel remarkably like understanding.
There will be times when learning must yield to urgency.
During an active incident, we may need the fastest reliable path to containment. That is a reasonable operational decision. Turning every action into a lesson could make the situation worse.
But if urgency displaces learning, a retrospective should be required.
Give it an owner and a place on the calendar. Preserve the evidence, decisions, uncertainties, and outcomes needed to reconstruct the incident. Otherwise, “we will learn from this later” becomes something we say while moving to the next emergency.
The retrospective should do more than replay the agent’s finished explanation. Revisit what was known at each consequential decision. Let the learner propose a next step before revealing what actually happened. Examine which clues mattered, which assumptions failed, and what the agent or the humans overlooked.
We cannot recreate the original uncertainty perfectly. We can still give people a meaningful encounter with the choices that urgency prevented them from making.
For designers of these systems, I would carry six principles into the work:
1. Preserve decisions worth practicing. Identify where the task develops judgment. Automate the routine preparation while giving learners opportunities to choose hypotheses, seek evidence, and interpret results.
2. Make room for an attempt before the answer. Let people predict, investigate, or create before presenting the completed solution. Offer hints and graduated assistance so being stuck does not always end with the agent taking over.
3. Design the human’s role around expertise. Decide what the person contributes to the inner or outer loop, and make room for that role to change as they teach and learn. Make assumptions and supporting evidence available for inspection. A change in conversational role should never silently expand the agent’s authority.
4. Provide a safe place to practice. Use simulations, historical cases, isolated environments, and reversible actions where appropriate. Let people make consequential choices within conditions that contain the cost of being wrong.
5. Require a retrospective when urgency displaces learning. Assign responsibility, preserve the decision history, and return to the case. Treat that learning as part of completing the incident.
6. Measure growing capability alongside completed work. Examine whether people can handle unfamiliar cases, explain uncertainty, identify an incorrect recommendation, and work with less assistance over time. Throughput alone cannot tell you whether an apprenticeship is working.
These principles need organizational support. If we reward only approvals per hour, people will have good reasons to skip the learning step. Designers can create an opportunity to practice; managers must allow people to use it.
AI could make expert guidance more available than it has ever been. A patient assistant could help someone explore more cases, receive faster feedback, and understand mistakes that would otherwise remain mysterious.
That is an extraordinary opportunity for craftsmanship.
But we have to design for it. A workflow can complete the task so thoroughly that the beginner has almost nothing left to do except accept the result.
Before building that workflow, ask what tradecraft the task used to develop—and where a beginner will now practice it.
Give them an instrument. Give them room to play.
Mahalo for reading!
Aloha –TK

