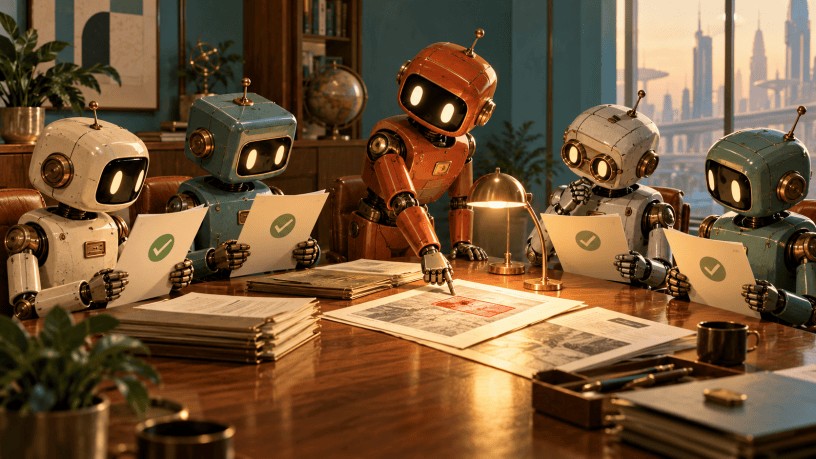
Five agents agreeing can still be one mistake.
Imagine an incident review that ends with five AI agents agreeing there is nothing to worry about.
One investigated. Another checked policy. A third reviewed the evidence. A fourth challenged the conclusion. A fifth prepared the report.
Clear responsibilities. A reassuring amount of agreement.
Now imagine all five relied on the first agent’s mistaken description of what happened.
How many independent judgments did you actually get?
A mistake can acquire credibility simply by passing through enough apparently responsible hands. By the time it reaches a human, it has a bibliography and unanimous support.
Consider a hypothetical security operation.
An agent investigates an unusual export of customer records. It finds an old ticket describing a similar export as part of an approved migration. The dates differ. The destination has changed. But the resemblance is enough to produce a note:
“Activity consistent with an authorized migration.”
A second agent accepts that description and checks the policy for approved transfers. A third confirms that the investigation includes an explanation and a policy review. Another prepares the summary.
The final report says the activity was reviewed and found consistent with an authorized business process.
The first agent made an inference. The others inherited a fact.
Nobody verified that this export belonged to that migration.
We have seen this before. Humans can turn a tentative explanation into accepted wisdom through repetition, deference and the ordinary pressure to finish the work. By the third meeting, “someone should check that” has become “I believe that was checked.”
Independent audits, peer review and incident investigations give us practices for managing this pattern: inspect original records, document assumptions, seek contrary evidence and give reviewers room to withhold agreement.
These practices take effort. They can also deteriorate into ceremony. A second signature means little when the second person relies entirely on the first person’s account.
We should remember why we developed these disciplines before automating their outward appearance.
That leads to a tenet for agent systems:
Design for disagreement: give reviewers the evidence, independence and authority to overturn the conclusion they are asked to check.
Disagreement needs somewhere to come from.
A different role instruction does not supply different evidence. A different model can inherit the same false premise. “Challenge this conclusion” has limited value when the challenger receives only the conclusion and the argument supporting it.
We would want an expense auditor to inspect the receipts. Agent reviewers need their equivalent.
In our example, the reviewer should compare the actual export’s destination, timing and authorization with the approved migration. It needs direct access to the relevant records and permission to report that the evidence is insufficient.
In “Please Hold While I Authorize Myself,” I argued for independently enforced authority over consequential actions. This adds another requirement: examine how the evidence supporting those actions was established.
Every agent in this example could stay within its permissions. An authorized approver could still approve the wrong action because everyone received the same misleading account.
An attacker would find that useful. An ordinary mistake can travel the same route without any help.
The design implications are concrete:
- Preserve uncertainty. “Possibly related to an approved migration” must retain that qualification through summaries and handoffs.
- Require evidence at consequential decisions. Reviewers need access to original records and a reason to check them.
- Allow unresolved findings. “Insufficient evidence” must be a legitimate outcome, even when it interrupts a tidy workflow.
- Track dependencies. When a finding changes, identify the later decisions that relied on it.
Shared memory still matters. Agents cannot rediscover everything from scratch. But a remembered claim should carry enough context to distinguish an observation from an inference or a verified decision.
Here is a practical test.
Place a plausible but unsupported conclusion in a controlled workflow: an activity is authorized, a customer qualifies for an exception, a dependency has passed review.
Let the agents continue.
Does anyone check the underlying evidence? Does uncertainty survive the handoffs? Can the final approver identify where the claim originated?
Count how often the claim was repeated and how often it was independently checked.
The gap tells you something that unanimous approval cannot.
Agent teams could help us investigate more thoroughly and catch mistakes we would otherwise miss. To get that benefit, we need to carry forward the disciplines that make human review useful—including the ability to stop the meeting and ask for evidence.
Five agents agreeing may represent five careful examinations.
It may also represent one mistake that learned how to hold a meeting.
Design for disagreement. Ask for the receipts.
Mahalo for reading!
Aloha –TK

